
AI Summary
This video provides a concise overview of Big-O notation, explaining how it measures algorithm efficiency by scaling with input size. It covers common complexities from fastest to slowest, and emphasizes that real-world performance is also influenced by hardware factors like caching and memory locality.
Chapters
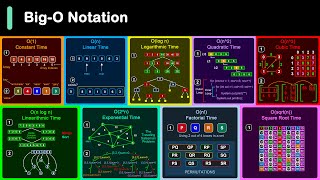
Big-O measures how execution time scales with input size, crucial for optimizing code performance.
Runtime remains constant regardless of input size; examples include array indexing, hash table operations.
Runtime increases slowly with input size; binary search is a classic example, efficient for large datasets.
Runtime grows directly proportional to input size; e.g., finding max in an unsorted array.
Efficient sorting algorithms like merge sort, quicksort, heapsort operate here; best possible for comparison-based sorting.
Runtime grows proportional to square of input size; basic sorts like bubble sort, indicated by nested loops.
Runtime grows proportional to cube of input size; naive matrix multiplication is an example, often three nested loops.
Runtime doubles with each additional input element; seen in some recursive algorithms, impractical for large inputs.
Runtime grows extremely fast; generating all permutations is an example, impractical for non-trivial input sizes.
Big-O is just a start; caching, memory usage, and hardware specifics can affect actual performance. Maximizing cache hits can sometimes be more effective than reducing algorithmic complexity.
Row-wise traversal of a 2D array is often faster than column-wise due to sequential memory access and cache friendliness, despite both being O(n^2).
Both have linear traversal time, but arrays often outperform linked lists due to cache locality—elements are stored contiguously.
Use Big-O as a starting point, but profile your code, understand your hardware, and optimize for real-world conditions.
Big-O notation is essential for understanding algorithmic efficiency, but real-world performance depends on hardware factors like caching and memory layout. Always profile and optimize for actual conditions.
Mentioned in this Video
Study Flashcards (7)
What does Big-O notation measure?
easy
Click to reveal answer
What does Big-O notation measure?
How execution time scales with input size.
00:02
Give an example of an O(1) operation.
easy
Click to reveal answer
Give an example of an O(1) operation.
Array indexing or hash table lookup.
00:18
What is the time complexity of binary search?
easy
Click to reveal answer
What is the time complexity of binary search?
O(log n).
00:32
Which sorting algorithms achieve O(n log n) time?
medium
Click to reveal answer
Which sorting algorithms achieve O(n log n) time?
Merge sort, quicksort, heapsort.
01:00
What indicates quadratic time complexity in code?
medium
Click to reveal answer
What indicates quadratic time complexity in code?
Nested loops iterating over the same data.
01:14
Why might row-wise traversal of a 2D array be faster than column-wise?
medium
Click to reveal answer
Why might row-wise traversal of a 2D array be faster than column-wise?
Row-wise maximizes sequential memory access and is cache-friendly.
02:08
Why do arrays often outperform linked lists for traversal despite same time complexity?
medium
Click to reveal answer
Why do arrays often outperform linked lists for traversal despite same time complexity?
Arrays have better cache locality due to contiguous memory storage.
02:22
💡 Key Takeaways
Big-O Definition
Establishes the core concept that Big-O measures scaling with input size, essential for performance optimization.
00:02O(n log n) Sorting
Identifies the best possible time complexity for comparison-based sorting, a key fact for algorithm selection.
01:00Real-World Factors
Highlights that Big-O is not the only factor; caching and hardware can significantly impact performance.
01:56Cache-Friendly Traversal
Demonstrates a practical example where cache optimization can outweigh algorithmic complexity.
02:08Full Transcript
[00:02] ключ к пониманию эффективности алгоритмов. Big O измеряет, как время выполнения масштабируется в зависимости от размера входных данных, что имеет решающее значение для оптимизации производительности Cod. Давайте разберем распространенные обозначения от самого быстрого к самому медленному. Время выполнения за постоянное время
[00:18] остается неизменным независимо от размера входных данных. Индексы массивов, операции с осью или хеш-таблицей — хорошие примеры. Время выполнения за логарифмическое время примеры. Время выполнения за логарифмическое время медленно увеличивается по мере роста входных данных; бинарный
[00:32] поиск — классический пример. Эффективен для больших наборов данных; удвоение размера входных данных — всего лишь еще одна операция. Время выполнения за линейное время растет прямо пропорционально входным данным, например, поиск максимума в несортированном массиве. Если вам необходимо
[00:48] обработать каждый элемент, то здесь начинается линейное арифметическое время. Именно здесь работают эффективные алгоритмы сортировки: сортировка слиянием, быстрая сортировка, пирамидальная сортировка — наилучший из
[01:00] возможных вариантов для сортировки на основе сравнений. Время выполнения за квадратичное время растет пропорционально квадрату размера входных данных. Базовые алгоритмы сортировки, такие как пузырьковая сортировка, — обратите внимание на вложенные циклы, итерирующие по одним и тем же
[01:14] данным. Время выполнения за кубическое время растет пропорционально кубу размера входных данных. Наивное умножение матриц — хороший пример. Три вложенных цикла часто указывают на кубическое время.
[01:26] экспоненциальное время, удваивающееся с каждым дополнительным входным элементом. Вы увидите это в некоторых рекурсивных алгоритмах. Обработка небольших входных данных может занять много времени. Факториальное время, удваивающееся с размером входных данных, чрезвычайно быстро растет. Генерация всех
[01:42] перестановок помещается здесь. Непрактично для нетривиальных размеров входных данных. Теперь вот нетривиальных размеров входных данных. Теперь вот важная часть: BigO — это только начало. Производительность в реальных условиях может отличаться из-за таких факторов, как кэширование, использование памяти и
[01:56] особенности оборудования. В современных процессорах максимизация попаданий в кэш иногда может быть более эффективной, чем снижение сложности алгоритма. Два примера: первый —
[02:08] сложности алгоритма. Два примера: первый — обход массива. Рассмотрим двумерный массив. Обход по строкам часто быстрее, чем по столбцам, хотя оба варианта имеют квадратичную временную сложность. Построчная ось максимизирует последовательный доступ к памяти и
[02:22] последовательный доступ к памяти и дружественна к кэшу. Далее — связанный список против массива. Оба имеют линейную временную сложность для обхода, но массивы часто превосходят связанные списки из-за локальности кэша. Элементы массива расположены последовательно в памяти, в то время как элементы
[02:35] связанного списка могут быть разбросаны. Итак, какой ваш вывод? Используйте PiO в качестве Профилируйте свой код, понимайте свое оборудование и оптимизируйте его для реальных условий, если хотите.
[02:50] Возможно, вас также заинтересует новостная рассылка по системному проектированию, которая охватывает темы и тенденции в проектировании крупномасштабных систем. Ей доверяют 1 миллион читателей. Подпишитесь на этот million readers subscribe that blog blog. byby go.com