
AI Summary
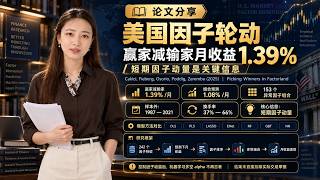
This video analyzes a finance paper that uses machine learning to predict factor returns in the US equity market. The study constructs 153 long-short anomaly portfolios and uses 242 features to forecast next-month returns, finding that a simple penalized linear model achieves an out-of-sample R-squared of about 0.6% and generates monthly return spreads up to 1.39% between top and bottom predicted factor deciles. The key insight is that most predictive power comes from factor momentum, not complex nonlinear relationships.
Chapters
The paper examines whether factor returns can be predicted in advance using machine learning on past returns, risk, and spreads across 153 US long-short anomaly portfolios.
The predictive ability of the model decreases over time, and most of the predictive information comes from factor momentum.
Penalized linear models achieve an out-of-sample R-squared close to 0.6%, which is modest in absolute terms but significant at the factor level.
Sorting factors into deciles by predicted returns, the high-minus-low portfolio yields monthly returns up to 1.39%, and these returns are not fully explained by common risk factors.
Most predictive information is concentrated in a few variables related to factor momentum, not spread across the 200+ features.
Unlike prior studies that look at single predictors, this paper jointly evaluates a wide set of signals, letting the data determine which variables matter.
The study uses stock data from CRSP and Compustat, covering January 1972 to December 2021 (600 months), with only common stocks, value-weighted, rebalanced monthly.
The five factor universes follow the framework by Jason Kelly and Patterson (2023), ensuring broad coverage.
The paper includes 242 factor features covering past returns (1-60 months), spreads, and risk, without pre-selecting a small set of predictors.
The problem is framed as a conditional expectation of next-period returns given a 142-dimensional information vector, with a focus on relative ranking rather than precise return levels.
Seven machine learning models are compared, including OLS, LASSO, elastic net, random forest, gradient boosting, regression trees, and neural networks, plus a combination forecast.
An expanding window approach requires at least 15 years of in-sample data (10 years training, 5 years validation), with 12 months held out for testing, and hyperparameters re-estimated annually.
Unregularized OLS overfits severely with 242 features, while LASSO and elastic net achieve ~0.6% out-of-sample R-squared, highlighting the importance of regularization.
Random forests, boosting, and neural networks show little improvement over regularized linear models, likely due to limited observations or weak nonlinear interactions.
Factors are sorted into deciles by predicted returns, and a winner-minus-loser portfolio is built, with alpha calculated using the Fama-French six-factor model.
Gradient boosting regression trees achieve the highest winner-minus-loser monthly return of 1.39%, while the combination forecast yields 1.08%.
Returns remain significant after six-factor adjustment, indicating they are not merely compensation for traditional risk exposures.
The combination forecast shows a monotonic increase in alpha across deciles, indicating the model provides useful ranking information even for middle groups.
The paper acknowledges that reported returns do not account for trading frictions, with average monthly cross-factor turnover of 37% to 66% for top and bottom deciles.
High-minus-low returns were 1.24% to 2.05% in the early sample (1987-2004) but fell to 0.30% to 0.95% in the later period (2004-2021), suggesting decay after discovery.
Results remain positive across nine combinations of decile, quintile, and tercile breakpoints, confirming the effect is not dependent on specific grouping choices.
The most important predictors are past factor returns, especially one-month returns, consistent with short-term factor momentum. Momentum-related spreads also rank high.
For LASSO and elastic net, the top three variables explain ~34% of predictive importance, and the top ten explain ~55%; for gradient boosting, the top ten explain ~59%.
Controlling for factor momentum makes all machine learning alphas statistically insignificant, indicating that the predictive information is almost entirely captured by a simple momentum variable.
The paper concludes that factor returns are predictable, simple regularized models are competitive, and the economic signal is strong but weakening, with factor momentum as the dominant mechanism.
The video concludes that machine learning can effectively rank factors for dynamic selection, but the core predictive power stems from a simple, interpretable momentum effect. Investors should be aware of declining predictability and transaction costs when implementing such strategies.
Mentioned in this Video
💡 Key Takeaways
Out-of-Sample R-Squared
Demonstrates that factor returns are predictable at a meaningful level, despite the modest R-squared.
00:50Simplicity of Models
Challenges the assumption that complex models are always better, showing regularized linear models are competitive.
05:25Factor Momentum Dominance
Reveals that a simple momentum variable explains almost all predictive power, simplifying the investment process.
11:06Predictability Decay
Highlights the real-world challenge of alpha decay after discovery, important for strategy implementation.
08:26Full Transcript
[00:00] 在金融期刊上的论文,题目围绕在因子世界中挑选赢家 这篇论文研究的是因子收益能否被提前预测 作者用机器学习方法从过去收益、风险和价差中提取信息
[00:14] 并在153个美国多空异常组合上做了系统检验 论文显示,预测收益最高的因子组相比最低组 月度收益差最高可以达到1.39%
[00:26] 同时预测能力随时间有所下降 而且大部分预测信息来自因子动量 在诺文研究的问题很直接 就是因子收益在前面上能不能被预测
[00:38] 作者构建了153个 美国多空议程投资组合 用242个收益价差和风险特征 来描述每个因子 再用机器学习模型 预测下个月的因子收益
[00:50] 诺文发现 惩罚现行模型的样本外 预测R平方接近0.6% 这个数字虽然看起来不大 但在因子层面已经相当可观 按照预测收益把因子分成十组
[01:03] 高减低投资组合的月度收益 最高可以达到1.39% 而且收益差异 不能完全被常见风险因子解释进一步的分析表明 大部分预测信息并不是分散在200多个特征里
[01:17] 而是集中在少数与因子动量相关的变量上 陈乐文从因子选择问题说起 指出因子和智能Beta投资组合已经越来越像可投资的积木 投资者面对的异常现象越来越多
[01:30] 于是如何选出未来表现更好的因子就成了新问题 此前研究通常只看单个预测变量 比如动量、季节性、估值价差、波动率或者Beta 而这篇论文的做法是联合评估一个很宽的信号集合
[01:43] 让数据自己决定哪些变量重要 这样做的意义和预测个股不同 作者并不是要精确判断某只股票涨多少 而是希望动态增持一期收益高的因子 同时低碰一期收益差的因子
[01:57] 从而把预测信息转化成可操作的因子配置方案 在本部分作者选取了153个股票特征来构造多空一长 投资组合底层股票数据SCRSP和CompostTech
[02:11] 让本期从1972年1月到2021年12月整整600个月 让本只保留普通股组合按照数值加权 并且每月再平衡每个月对每个特征都要把股票排序
[02:23] 继而形成多空组合 预测测试的第一个年份是1987年 重视期从1987年到2021年 总共得到420个 每月测试观测值每个月有153个因子
[02:36] 五个因子宇宙遵循的是 Jason Kelly和Patterson 在2023年提出的框架 这样能保证覆盖链足够广 这篇论文在特征设计上的原则是
[02:48] 不提前人为挑选一小撮天号的预测变量 而是把多种替代定义和不同回复窗口都放进去 最终得到242个因子特征 涵盖过去收益特征价差和风险三类信息
[03:02] 其中过去月度收益有1到60个月的不同之后版本年度收益有6到20年的版本波动率也分成日度和月度不同窗口还有153个对应各自异常特征的价差变量
[03:15] 以及不同期限的市场 Beta 60个月的 作者让机器学习负责选择和加钱 而不是由研究者主观指定哪些变量重要 这正是孟仁强调的数据说话思路
[03:27] APART 我预测框架部分 把问题写成一个条件期望收益的形式 对月份T的因子I来说 下期收益聚集于10.T 可获得的142维信息向量
[03:41] 作者的目标是 估计这个条件期望收益 同时在较小的因子面板中控制过 米核最小化量的外平方预测误差 这里有一个关键解释 这个预测主要是一种相对排序信号
[03:55] 并不需要精确预测收益水平 只要能有效区分哪些因子会跑赢 哪些会跑输 就足以用于因子选择 只要哪些会跑输就足以用于因子选择
[04:07] 就是即使下节用于审子是打些因子会跑赢 哪些会跑输就足以用于因子选择性成真 在因子后轮评价模型时
[04:19] 更看重排序产生的组合收益差异 而不是预测本身的绝对误差 我一共比较了七类机器学习模型 加上组合预测 包括普通最小二乘
[04:31] 先追找二层 ASO弹性网络 随机增灵 梯度提升 回归数和前馈神经网络 最后再把所有单模型预测起平行形成组合预测 时间验证采用扩展窗口
[04:44] 要求至少15年的样本内预始 其中10年训练加5年验证之后 12个月留作测试模型 每年重新估计一次超参数在验证数据上选择 这样可以避免在测试期使用未来信息指他
[04:59] 这个设计让不同复杂度的模型都在同一标准下 比较样本外表现 首先整身型方面 乐乐发现 未正则化的普通最小二成 在242个特征的面板里严重过礼盒
[05:13] 样本外表现很差 相比之下 LASSO和弹性网络 实现了大约0.6%的样本YR平方 说明正则化在这一步非常关键 更复杂的分性性模型 比如随机森林
[05:25] 提升术和神经网络 相较于正则化线性方法 几乎没有改善 对各股领域的经验形成对比 作者解释可能是因为因子面板的观测数量有限 或者因子之间的非线性交互本来就不强
[05:39] 因此简单线性惩罚模型反而更合适 一简单的做法是 每个月按照模型给出的预期收益 把153个因子排序 然后分到10个预测收益十分位组里
[05:52] 再构建赢家减数加投资组合 为了判断这些收益不是来自已知风险暴露 作者同时用Fama和French六因子模型计算α 还用一个等权持有全部153个异常的朴素基准来对照
[06:07] 看动态选择是否真能超越简单平均 在经济学上的严格标准 是预测能否在因子组合之间产生单调的实际收益而不是只在某一两个极端组合里有效这样可以把统计上的预测能力转化为投资者真正关心的组合表现在对比显示
[06:26] 除了普通罪者二层之外 其他模型给出的预测都能区分 赢家因子和输家因子 梯度提升回归数的赢家减输家 阅读收益最高达到1.39% 组合预测的阅读收益为1.08%
[06:40] 惩罚线性模型近于中间 更重要的是 这些收益经过六因子调整后仍然显着 说明他们不只是承担了市场规模或价值等传统风险换来的 论文的表述是预测能够转化为成功的因子选择策略
[06:56] 而且这种效应在多个模型设定下都存在 并非单个算法的偶然结果 符合预测 把七种单独方法的预测进行平均论文发现 按符合预测收益排序后六
[07:09] 因子 阿尔法和等权积的阿尔法都行预测收益单调上升 这意味着效应不是只集中在最高或最低的极端组合里 而是从低到高呈现一种广泛且有序的结面模式
[07:22] 组合预测的做法也降低了单一模型过拟合的风险 让排序信号更加稳定了 对到投资者来说 这种单调性很重要 因为它说明模型不仅能找到最好的和最差的因子
[07:36] 还能对中间部分给出有区分度的排序信息 从而支持更细致的权重配置 这档实例 作者承认动态选择与静态异常配置存在实质差异
[07:48] 报告的收益还没有扣除真实世界的交易摩擦 交易成本和因子的可投资性仍然是重要考量 尤其是因子轮动需要频繁调整组合时 论文给出了换手率
[08:01] 发现顶部和底部十分未组的平均月度跨因子换手率 大约在37%到66%之间 这意味着维持赢家险输家组合每年会产生相当可观的交易量
[08:13] 或者没有回避这一点 而是把换手作为实施成本的重要参考 提示读者在解读收益时需要把这些摩擦考虑进去 这些读者显示可依靠性在样本前半段更强
[08:26] 从1987年到2004年中高减低阅读收益范围大约在1.24%到2.05%之间 而到了2004年中至2021年这个数字回落到0.30%到0.95%
[08:40] 论文的结论是收益和阿尔法仍然可观 但规模在后期样本中大约减大 它说明因此收益的可预测性在被发现之后有所衰减 可能与更多资金涌入因此错的有关
[08:53] 但即便如此 后期样本中的表现并没有完全消失 模型依然能提供有效的排序信息 在文件性检验中 作者改变了购件投资组合的分组方式
[09:06] 即准设定在股票层面的异常购件 和因子层面的机器学习逃去中都使用十分位 而稳坚性检验覆盖了十分位 五分位和三分位的九种断点组合
[09:19] 结果在所有九种组合中都保持为正 说明赢家减输家的收益方向 不依赖于特定的断点选择更宽的价差自然产生更大的收益差异因为极端组之间的因子数量差距更明显排序信号也更容易表现出来
[09:37] 不结果在所有九种组合中都保持 不依赖于排序信号也更容易表现出来 分组越粗 收益差越大 在相应的组合分散度也越低
[09:50] 这是正常的权衡 变量重要性方面 论文用了一个直观的做法 而某个特征设为零后 看样本外 而平方下降多少 再重新缩放
[10:02] 使所有重要性之和为一 结果显示 领先预测变量主要是过去因此收益 其中一个月因此收益反复位居前面 这已既有研究中强调短期因此动量的结论一致
[10:15] 与动量相关的特征 价差也排在很高位置 比如多空腿 历史收益的差异 相比之下 估值内价差和风险波动率变量的贡献 要少不多 这个发现百年变相看很复杂的
[10:28] 242位预测问题 压缩到了少数几个核心信号上 重要性在242个输入变量之间 远不是均匀分布的 对于拉索和弹性网络前三个变量
[10:40] 就解释了大约34%的预测重要性 前十个变量解释大约55% 对于季度提升回归数 前十个变量占比约为59% 这说明少量与动量相关的信号
[10:54] 驱动了进行询习表面优势的大部分 其他变量更多是补充性的微调 这个分布模式也解释了 为什么简单正则化模型就够了 因为真正有用的信息集中模型
[11:06] 不需要复杂结构去捕捉 分散在大量变量里的若非信息关系 我弄清楚预测的来源 作者做了因子动量涵盖解决 因子动量被定义为相对于历史经济的近期12个月表现
[11:21] 每个月按这个指标把因子分成三组 构造高减低因子动量组合 然后把每个机器学习投资组合 对因子动量组合回归 发现0加减数加 机器学习组合有正的因子动量载荷
[11:35] 而且一旦控制因子动量 所有机器学习高减低组合的alpha 在统计上都变得不显著 也就是说 魔术学会的排序信息 几乎全部可以被一个简单的因子
[11:48] 动量变量解释 这种简易性是论文最重要的机制发现 结论部分总结了三点 第一 因子收益确实存在 绝面可逆特性 惩罚回归 实现接近0.6%的样本外阿平方
[12:03] 预测排序产生可观的赢加减输加收益 第二 简单的正则化模型非常有竞争力 非线性数模型和神经网络 在这个因子面板中的增量有限 第三
[12:15] 经济信号很强 但正在减弱 动态因子选择优异标准因子 基本可预测性在后期样本中下降 机制上因此动量是主导力量 变量重要性和航该检验都表明
[12:28] 它捕捉了机器学习因子选择组合 几乎全部的异常收益 实践上 机器学习能帮助被因子机会排弃 核心信息却是一种简约 且可解释的动量效应