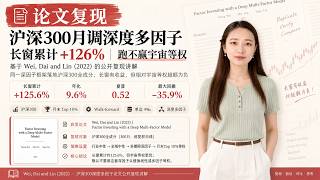

Deep因子策略年化仅9.6%,跑输基准
45s惊人对比:深度因子组合年化收益远低于简单线性策略,引发量化投资有效性讨论。
▶ Play Clip"The title promises a deep multi-factor study and delivers a thorough backtest analysis, though it is dense and technical."
This video presents a deep multi-factor stock selection study applied to the CSI 300 index, comparing a deep factor combination strategy against equal-weight and linear factor baselines. The analysis covers a rolling out-of-sample period from July 14, 2017, to September 11, 2026, with a focus on cumulative returns, annualized returns, Sharpe ratio, and maximum drawdown.
The deep multi-factor stock selection study is applied to a CSI 300 monthly rebalanced portfolio. From July 14, 2017, to September 11, 2026, the cumulative return is 125.6%, annualized 9.6%, with a Sharpe ratio of 0.52. The equal-weight benchmark for the same universe has an annualized return of 15.7%.
At each month-end, the strategy buys the top 10% of stocks by deep factor score within the CSI 300, holding them equally weighted. Transaction costs are 0.4% per side. The maximum drawdown is -35.9%.
The stock pool is fixed to the current 300 constituents of the CSI 300. The strategy selects from the top 10% by score, holding about 30 stocks. Inputs are 19 price-volume proxy factors including reversal, momentum, size, value proxy, volatility, and turnover. Industry relationships are built using 10-billion-level industry classifications, removing common market influences.
The strategy uses a rolling expanding window with about half-year test segments. Trading uses a 20-day lookback, buying the top 10% at month-end equally weighted. Turnover cost is 0.4% per side.
The backtest data differs from the original paper. The original uses official panels with 63 style factors including analyst expectations, while this study uses a quantitative terminal with daily lines and 19 price-volume proxy factors, without consensus expectations.
The backtest only uses current CSI 300 constituents, introducing survivorship bias. The industry classification is changed from the original's Zhongxin Level 1 to Shenwan Level 1. The backtest daily data spans from January 4, 2016, to September 11, 2026, with the main period starting July 14, 2017.
The results are based on rolling out-of-sample backtests with 18-fold expanding windows, date sampling, and parameter random perturbations. The results are only valid for this proxy data and training process, not as a substitute for the original paper.
The deep factor combination's long-sample cumulative return is 125.6%, but it consistently underperforms the equal-weight universe and the linear factor model. The linear model achieves a cumulative return of 630.2%, about 7 times higher, indicating the issue is ranking quality, not lack of growth.
The maximum underwater period is about 112 weeks, with a maximum drawdown of -35.9%. The experience is more like a high-volatility long-only strategy rather than a low-drawdown product.
All factor strategies are charged 0.4% per side, while the equal-weight universe is not charged, making the baseline slightly optimistic. Out-of-sample results show the deep factor combination has a long-sample cumulative return of 125.6%, annualized 9.6%, Sharpe 0.52, and short-sample cumulative return of 22.8%, annualized 16.8%, Sharpe 0.72.
The paper's comparison window shows a cumulative return of 86.9%, annualized 14.0%. The linear factor model achieves a long-sample cumulative return of 630.2%, annualized 25.2%, Sharpe 1.28.
The gap is significant. Even if the equal-weight universe is rebalanced monthly and adjusted for similar frictions, it cannot compensate for the disadvantage relative to the linear model. The report only discusses net-of-fee returns and performance metrics.
In the long sample, the linear factor model annualizes 25.2% with a Sharpe of 1.28 and max drawdown of -32.0%, comprehensively outperforming the deep factor combination's 9.6%, 0.52, and -35.9%. In the short sample, the linear factor equal-weight annualizes 28.5%, Sharpe 1.27, max drawdown -13.2%, while the deep factor combination only achieves 16.8%, 0.72, and -19.2%.
Even in the comparison window ending June 30, 2022, the deep factor combination annualizes 14.0%, still below the equal-weight universe's 17.7%. The underperformance is not recent.
The monthly top 10% equal-weight with 0.4% per side cost and rolling out-of-sample process can be retained as a basic framework. The linear factor model, with a cumulative return of 630.2%, annualized 25.2%, and Sharpe 1.28, should be prioritized for testing. To improve deep factor research, expand factor information, improve historical constituent handling, and test industry classification and training changes.
Capital allocation should account for a maximum drawdown of -35.9% and an underwater period of about 112 weeks. This strategy should not be viewed as a stable alpha product.
The strategy, applied to the current 300 constituents of CSI 300, buys the top 10% by deep factor score at month-end, equally weighted, with 0.4% per side cost. The rolling out-of-sample results show a long-sample cumulative return of 125.6%, annualized 9.6%, Sharpe 0.52, and max drawdown -35.9%, failing to beat the benchmark.
The deep factor combination underperforms both the equal-weight universe and the linear factor model. The linear model achieves a long-sample cumulative return of 630.2%, annualized 25.2%, and Sharpe 1.28.
The study's main contribution is to rule out a default choice: under the current 19 price-volume proxy factors and training process, linear or cleaner style weighting should be used instead of defaulting to deep factor attention heads.
The deep factor combination strategy underperforms both equal-weight and linear factor baselines, indicating that the deep factor attention head does not improve stock ranking quality. The study recommends using linear factor models as a default and further research to enhance factor information and handling of historical constituents.
Deep factor underperforms equal-weight
The deep factor combination's annualized return of 9.6% is significantly lower than the equal-weight benchmark's 15.7%, highlighting a ranking quality issue.
Linear model outperforms deep factor by 7x
The linear factor model achieves a cumulative return of 630.2% versus 125.6%, demonstrating that simpler models can be more effective.
02:25Benchmark gap cannot be closed
Even after adjusting for frictions, the equal-weight universe cannot match the linear model's performance, emphasizing the deep factor's disadvantage.
03:47Underperformance is historical
The deep factor combination has underperformed since at least 2022, indicating a persistent issue rather than a recent anomaly.
04:39Recommendation to avoid deep factor default
The study provides a clear, actionable recommendation to prefer linear models, guiding future research and strategy design.
06:18[00:00] 本期附现一篇深度多因子选古研究 我们把它落到护身300 月调组合上 2017年7月14日到2026年9月11日的 近累计只有125.6%
[00:14] 年化9.6% 下谱0.52 而同期同宇宙等全年化是15.7% 而策略每个月末按20日深因子得分买入 护身300里最高的10%
[00:27] 并等全持有 按单中千分之四扣除交易成本 最大回撤为负35.9% 结论指覆盖当前沪深300的300只成分
[00:39] 19个价量代理因子和滚动让本外窗口 本策略股票池固定为当前沪深300的300只成分股 约莫只从得分最高的10%里选股
[00:52] 约持有30只输入为19个价量分隔及衍生因子 包括反转动量、规模、价值代理、波动和换手 只用当日及以前价格成交 按千、十万亿级行业构建同业关系
[01:05] 并去除全市场共同影响 系列以滚动扩展窗约半年一个测试段 测试段是调用此前全数出分 交易端只用20日测头 月末等权买入最高的10%
[01:18] 换手按单边千分之四扩成本 大摆设和原矿价不是同一份数据 原矿价用官方面板 63个风格因子定含分析师预期 我们只用量化终端前赴全日线和19个价量代理因子
[01:33] 没有一致预期原矿价覆盖中正300 500 1000历史成分约两千八百只本回撤只取当前沪深三百的三百只存在存活偏差行业图
[01:46] 也从原矿价的中心一级 改成本回撤的深外一级 同业全连接 由2010年到2022年综本 回撤日线 从2016年1月4日 到2026年9月11日
[01:59] 主定值从2017年7月14日开始 并采用 18折扩展窗 日期抽息和参数随机导动更新 所以表格结果 只对本代理数据和本训练流程负责
[02:12] 不是原始格点的替代 变因 与深因子组合取建 是滚动样本外的扣备定值 事先后的2025年5月6日 到2026年9月11日 属于短样本观察
[02:25] 深因子组合长样本 近累计125.6% 却长期落在宇宙等权 和同因子线性之下 说明问题不是组合没涨 而是排序质量不够 同样的股票池
[02:38] 同样的月末最高10% 和同一组因子线性策略 长量本累计630.2% 约7倍进质量级 不生因子组合 最长水下约112周
[02:50] 最大混测负35.9% 体验更像高波动多头 而不是低混测二发产品 小一把 所有因子策略都按单边千分之四扣费
[03:02] 宇宙等全基本位扣费 所以基本表现略偏乐观 样本外组结果显示 深因子组合常样本累计125.6% 年化9.6%下谱0.52%最大回撤负35.9%软样本累计22.8%年化16.8%夏普0.72
[03:22] 论文对照窗累计86.9% 年化14.0% 同因子线性长 样本累计630.2% 年化25.2% 夏普1.28%
[03:34] 差距明显刀分的线性长 样本累计630.2% 年化14.0% 同因子线性长样本累计630.2% 年化25.2%
[03:47] 下谱1.28% 差距明显是100%的基准滋滋两气 即使把宇宙等权也按捩调仓 并补上相近摩擦 也补不回相对线性的劣势 所以本报告只讨论扣费后的净值和绩效指标
[04:02] 打长窗和短窗绩效并排比较长 样本里同因子线性年化25.2% 下谱1.28 最大回撤负32.0%
[04:14] 全面优于深因子组合的9.6% 0.52%和负35.9% 短样本中因子等全年化28.5% 下谱1.27 最大回撤负13.2%
[04:27] 深因子组合只有16.8% 0.72%和负19.2% 这说明今一年价量风格本身有几面机会 但除注意力深 因子头没有把它转化为更好的股票排序
[04:39] 直到2022年6月30日的对照窗 深因子组合年化14.0% 仍低于同期宇宙等权的17.7% 落势并非最近才出现 高层可以这样用月末最高的10%等权单边千分之四成本和滚动样本外流程可保留为月平选股基础框架
[05:01] 更值得优先测试的是 同因子信息模型 转让本累计630.2% 年化25.2% 下谱1.28 进行研究生因子投石 要先扩充因子信息
[05:14] 改进历史成分处理 并检验行业分类和训练器变化 资金配置 需按35.9%的最大回撤和约112周水下期预留预算 不能视为稳定Alpha产品
[05:27] 规格上不要默认用图 注意令深因子头替代线性或简单分隔加权 也不要把当前成分回撤外推为无存活偏差的食材收益
[05:40] 发病者的结论很直接 策略在呼声300 当前300只成分 每个月末按20日深因子折分买入最高的10% 并等权持有 单边成本三分之四可交易的滚动样本
[05:54] 外主结果为 长样本累计125.6% 年化9.6% 下谱0.52 最大回撤负35.9% 不去被替代基准的优势
[06:06] 生因子组合同时跑输同宇宙等权和同因子线性 其中线性长样本累计630.2% 年化25.2% 下谱1.28%
[06:18] 本研究的主要帮助是明确排除一个默认选择 在当前护身319个价量代理因子和这套训练流程下 并先用线性或更干净的风格加成
[06:30] 不要默认上升因子图注意力头
⚡ Saved you 0h 06m reading this? Transcribe any YouTube video for free — no signup needed.